
Every agent eval suite has one component nobody tests. You wrote careful scenarios, mocked the tools, and ran each one five times. Then you handed the final verdict to another LLM call and believed it.
That call is the judge. A wrong judge doesn’t fail your suite. It passes replies that should have failed, and nobody hunts for bugs in a green build.
Treat the judge like any other component. Give it a narrow contract and tests that pass before its grades count. Here are five rules, with examples in Python. The same shapes work in a TypeScript suite.
Share this post & I’ll send you some rewards for the referrals.
Your AI team has enough frameworks. Here’s what ships. (Partner)

Your team does not need another framework comparison. All Day AI brings 122 builders and technical leaders together to explain what survived production and what failed.
Agenda highlights:
See what broke when teams put agent swarms into production.
Learn why prompt injection is an architecture problem.
Follow how AI is changing software development from code to context.
The BUILD, LEAD, SECURE, and SHIP tracks also cover evals, model routing, permissions, AI coding costs, and failure-safe design. Sessions run for 30 minutes, so you can focus on the problems your team has now.
(Thanks to All Day AI for partnering on this post.)
1. Write criteria a human could check in five seconds
"The response is helpful and professional" is a vibe, and a judge will wave almost anything through it. "The response says the card will be blocked" is a fact you can check in five seconds. If a criterion takes longer, split it.
Keep three or four criteria per step, and ask about one criterion per judge call. When one prompt holds four criteria, the verdict on one sways the verdict on the next (Stureborg et al. 2024 measured this anchoring effect).
Store criteria as named rubrics in YAML, so every scenario reuses the same "card-blocking reply". Load them through a Pydantic model with extra="forbid". A typo in a field name then fails on load instead of quietly checking nothing.
2. Never ask the judge what code already knows
A judge is the slowest, most expensive, and least reliable check you have. Plain code answers which tools ran, what arguments the API got, and whether a refund total adds up. It's exact and free, and your mocked tools already log their calls.
Save the judge for meaning. "Your card ending in 4821 is now blocked" and "Done, I've blocked it" are both correct, and no regex covers that space. A criterion the judge keeps getting wrong usually belongs in code.
3. Count the threshold, never ask for a score
Sooner or later someone wants a number. Don't get it from the judge. In the same Stureborg study, models asked for a 1-100 rating put most replies between 70 and 100, bunched on round numbers, and shifted when the prompt was reworded.
Count binary verdicts instead:
A step: 3 of 4 criteria held → 75%.
A scenario: 4 of 5 runs passed → 80%.
The suite: 46 of 50 scenarios green → 92%, the number you gate a release on.
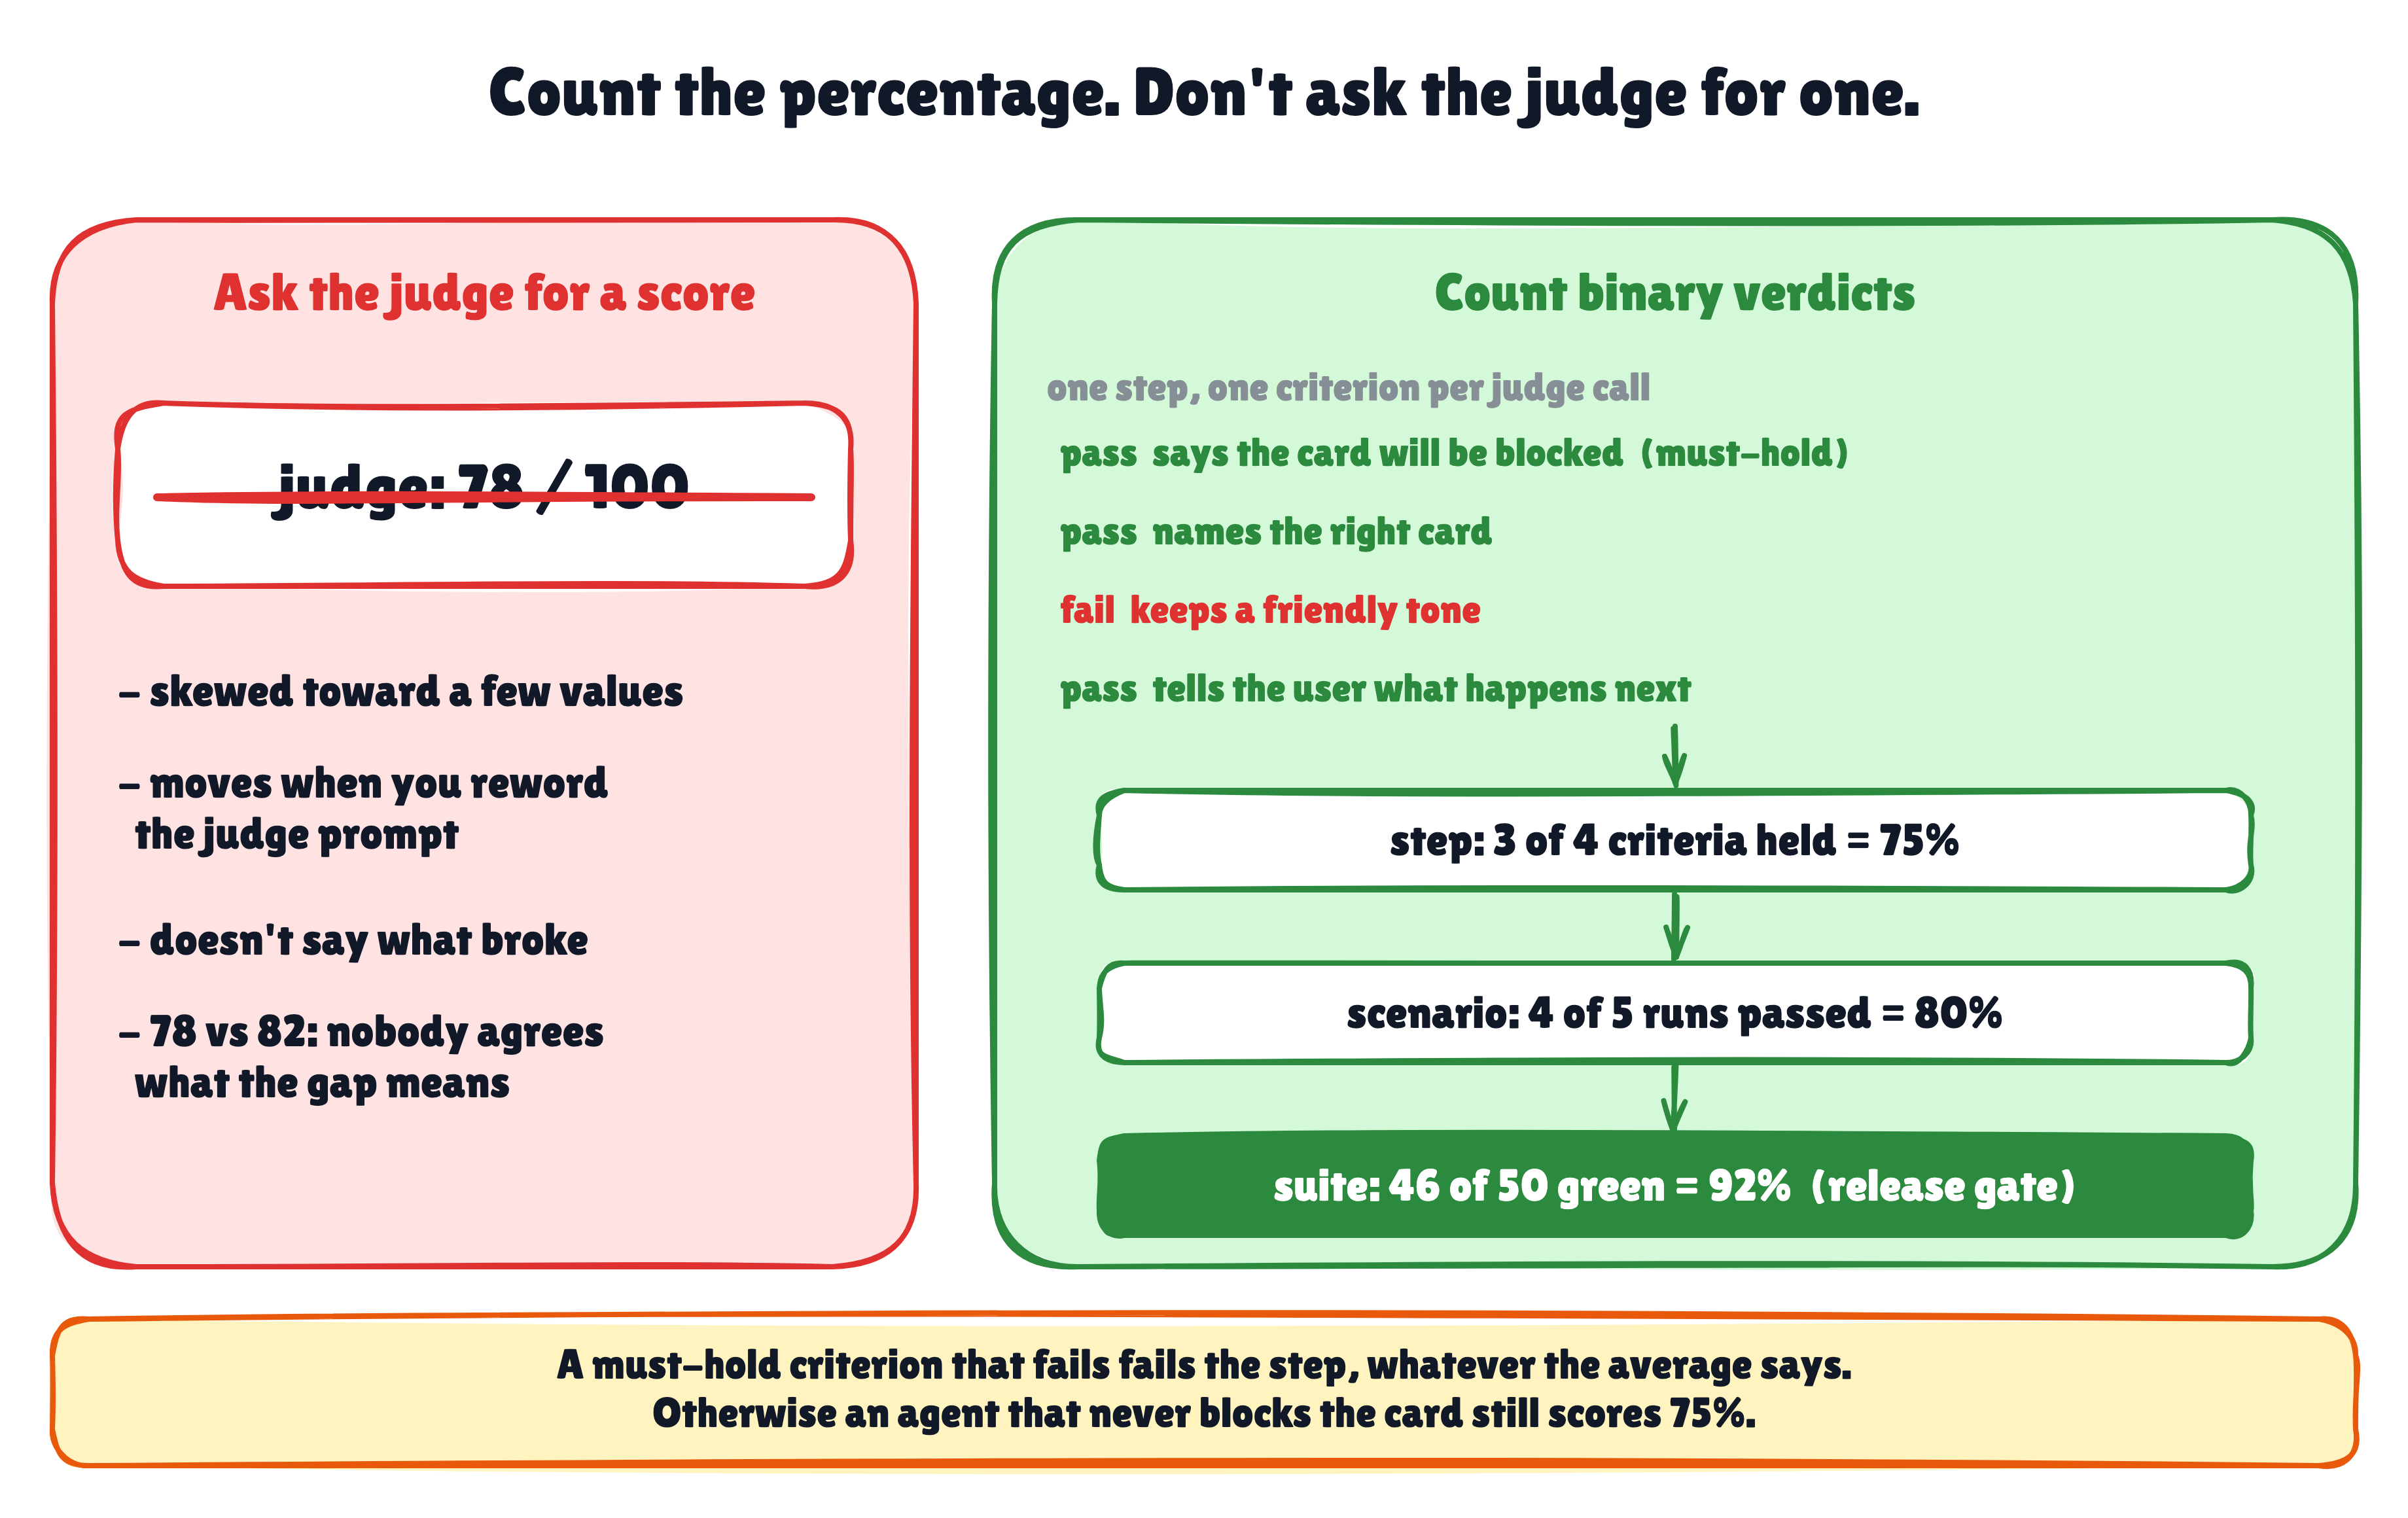
A drop in any of those traces back to the criterion that flipped.
Two caveats. Mark the must-hold criteria, because on a plain average, an agent that never blocks the card still scores 75%. One failed must-hold fails the step.
For something that isn't binary, like tone, use three labels (fails, partial, holds) rather than a hundred. A reviewer can tell "partial" from "holds". Nobody can defend 78 over 82.
4. Calibrate the judge, then gate on it
This rule makes the rest trustworthy. A calibration set is a handful of hand-written replies, some clearly good and some clearly bad, each labeled with the verdict every criterion should produce. Run the judge over them with no agent and no mocks, because the judge is what's under test:
# evals/judge.py
from typing import Literal

from pydantic import BaseModel


class Verdict(BaseModel):
    reason: str                     # what you read when a check fails
    label: Literal["pass", "fail"]  # the only two answers the judge can give


def judge(reply: str, criterion: str) -> Verdict:
    """One model call, one criterion, output parsed straight into a Verdict."""
    ...


# tests/evals/test_calibration.py
import pytest

from evals.calibration import load_calibration_cases
from evals.judge import judge


@pytest.mark.parametrize("case", load_calibration_cases(), ids=lambda c: c.name)
def test_judge_matches_hand_labels(case):
    for criterion, expected in case.expected_labels.items():
        verdict = judge(case.reply, criterion)
        assert verdict.label == expected, f"{criterion}: {verdict.reason}"
With that Literal as the output schema, the judge can't answer "mostly passes" or "8/10". Keep reason to one sentence. The structured-outputs docs warn that a field asking for step-by-step reasoning can trigger a refusal on current Claude models.
This test catches calibration drift. Someone rewords a criterion to fix one case, and a known-bad reply starts passing. Without the test, nothing tells you.
Small changes move judges a lot. Swapping only the order of two answers made GPT-4 flip its verdict on 46.3% of Vicuna-13B versus ChatGPT pairs, two closely matched models (Wang et al. 2023).
In a study of 13 judge models, most leaned toward "correct" when unsure (Judging the Judges). Lenient is the direction that turns a suite green. Those were older models, and your calibration set tells you how yours behaves.
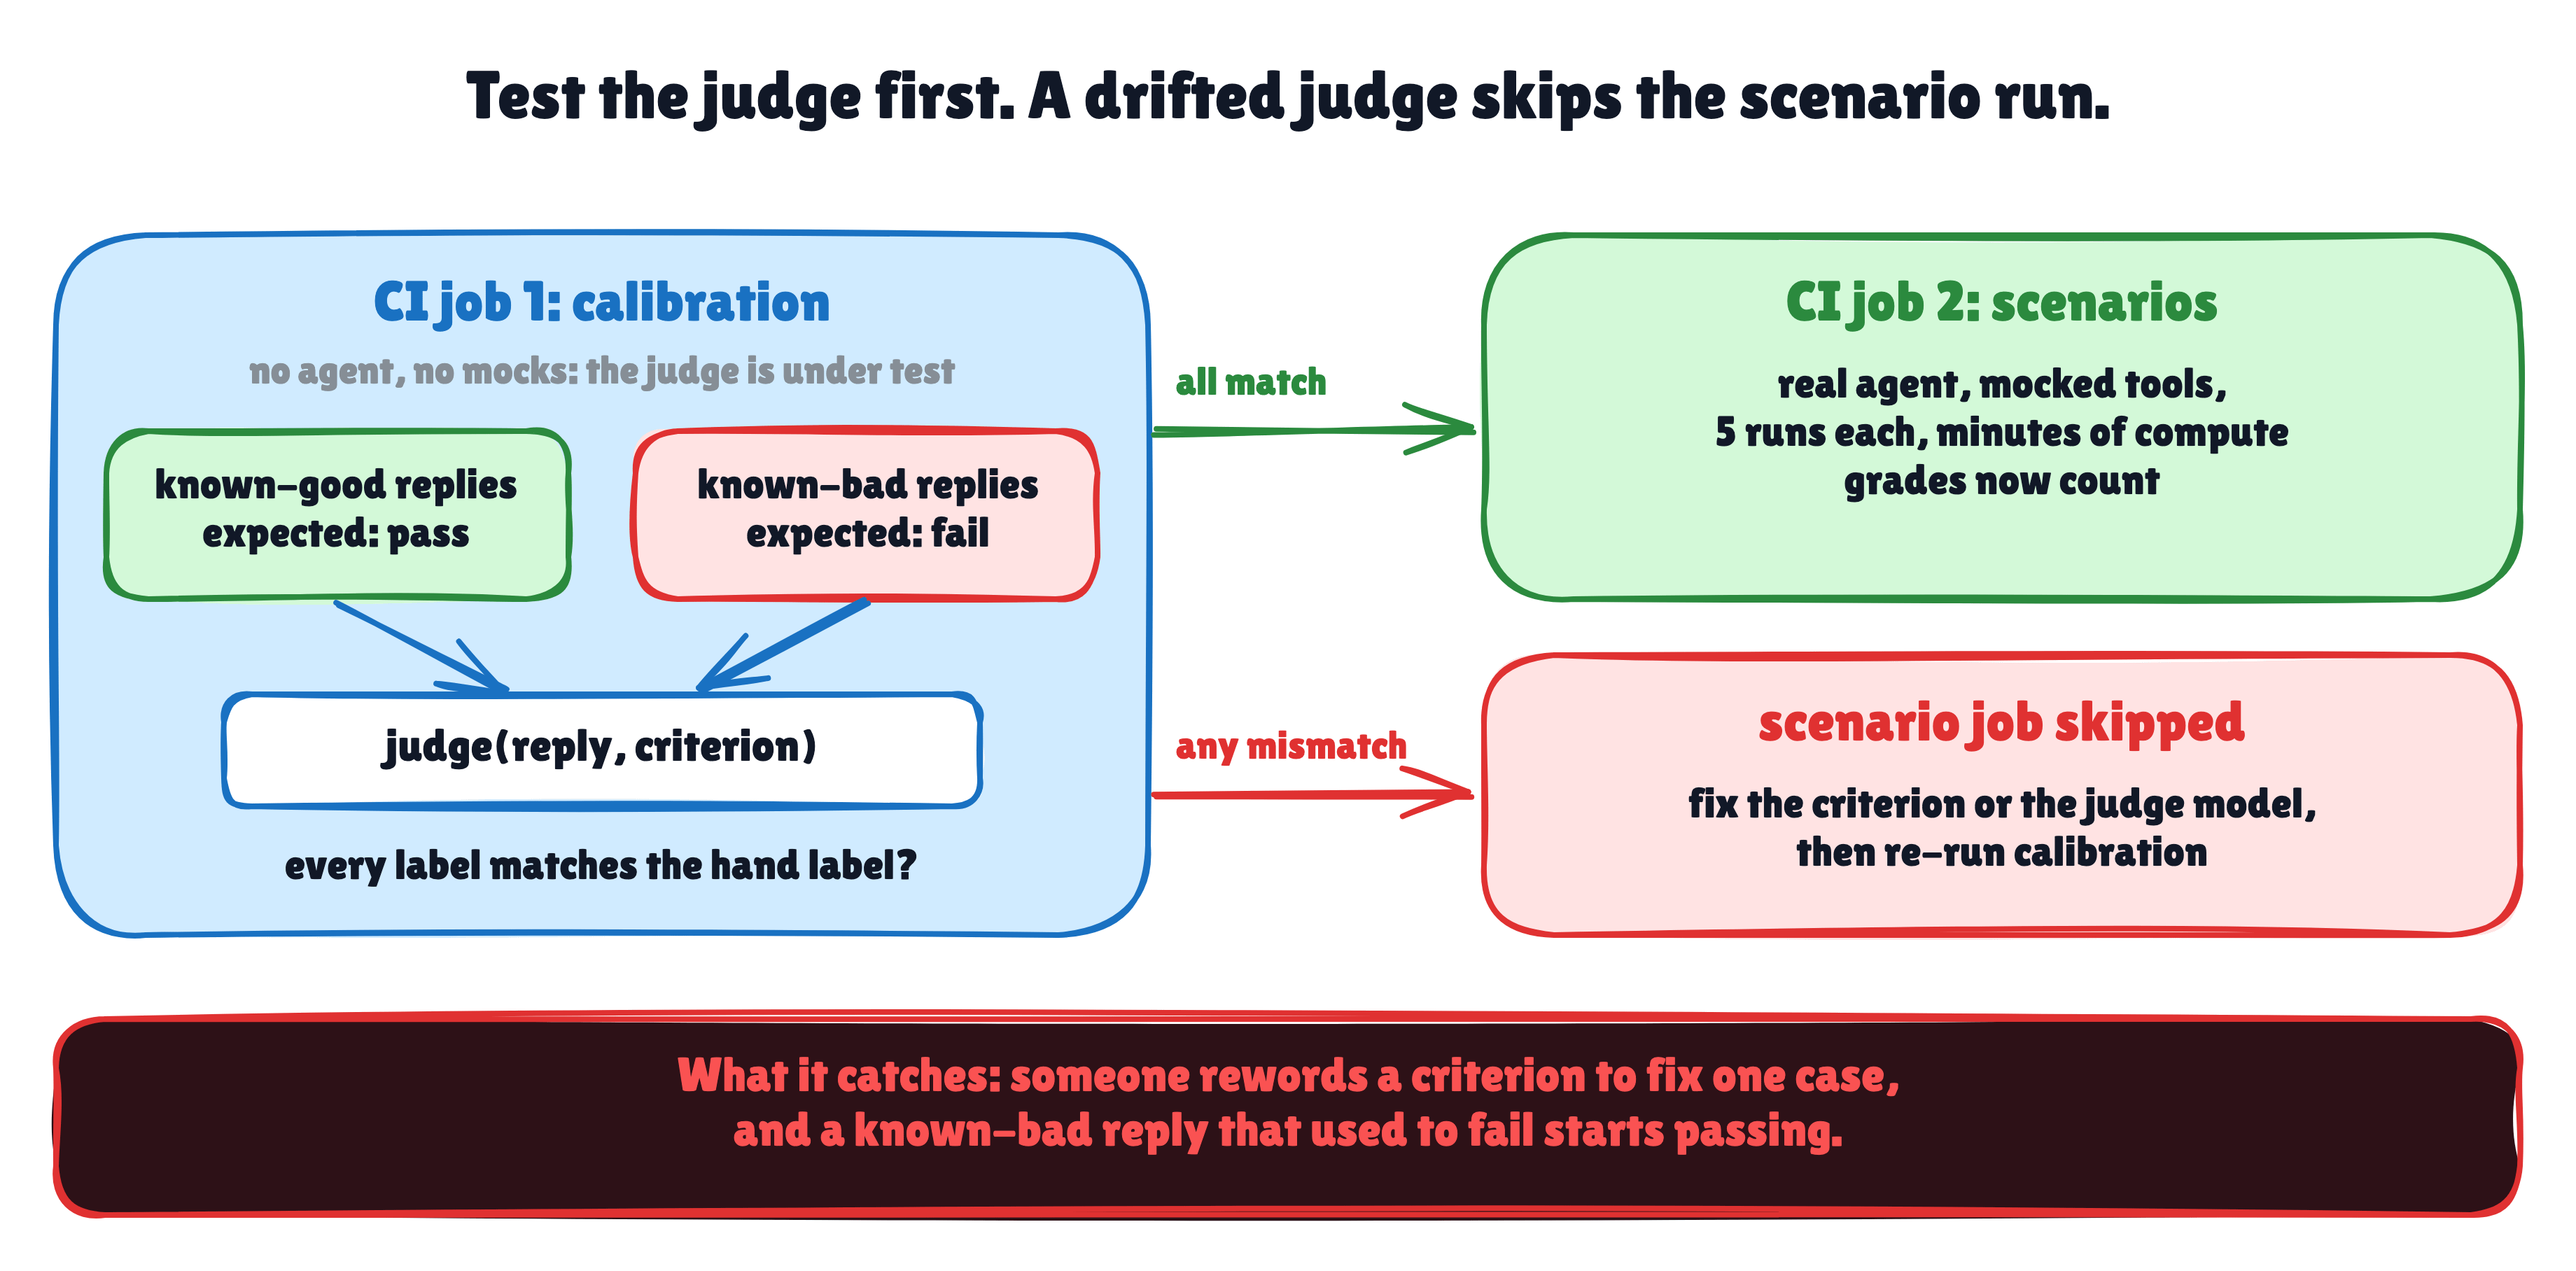
Run calibration as its own CI job, before the scenarios. If the judge fails, CI skips the scenario job, and you don't burn minutes of agent runs on a judge you know is broken.
5. Grade with a different model, and let calibration size it
LLM judges recognize and favor their own writing. Panickssery et al. found GPT-4 and Llama 2 tell their own text from other models' text better than chance, and the bias grew when fine-tuning improved that recognition.
Let the agent's model grade its own replies, and that bias leans toward passing. Use a different model, ideally from another family, because judges also favor related models (Preference Leakage).
A bigger judge isn't always a better one. A narrow yes/no check is easier than writing the reply, though in Judging the Judges only the largest judges came close to human agreement.
Judge calls also add up. Four criteria, five runs, and 50 scenarios make 1,000 calls for one graded step. Your calibration set settles the size question. If a cheaper judge passes it, it's good enough.
One more known bias. MT-Bench found judges swayed by the order they read two replies in, and two of its three judges fell for padded answers. Grading one reply at a time removes the order problem, and binary criteria make length matter less.
A green suite should mean the agent passed
The judge decides what "working" means. That makes it the last thing to trust on faith. Give it a narrow job, make it count instead of guess, and test it before it grades anything.
Do that, and a green suite means the agent passed. Skip it, and a green suite means the judge said so.
📌 TL;DR
Criteria a human can check in five seconds. Three or four per step, one per judge call.
Code checks what code knows. Tool calls, fields, and totals get exact checks. The judge grades meaning.
Count verdicts instead of asking for a score. Tally pass/fail across criteria, runs, and scenarios, and mark the must-holds.
Calibrate and gate. Hand-labeled replies run first in CI, and a failing judge skips the scenarios.
Grade with a different model, ideally from another family, sized by calibration.
Split out of The 3 Layers of Testing AI Agents, which covers the full three-layer setup these judges plug into.

Follow me on LinkedIn | Twitter(X) | Threads
Thank you for supporting this newsletter.
Consider sharing this post with your friends and get rewards.
You are the best! 🙏

Press the Like button if you found this post helpful
treating the judge like code that needs its own tests is the part i liked most. never thought about it that way, thanks.
Petar Ivanov makes the case that the AI model grading your agent is the least tested part of the whole suite, and a lenient one turns everything green. We hit a version of this when our automatic image check passed holiday images that a person then failed, mostly for a product label you couldn't read. His calibration step, a small set of hand-labeled good and bad answers the judge has to get right before its grades count, is the part I'd copy first. How often do you add a new case to that set?