
A customer places an order. You save it to Postgres, then publish an OrderPlaced event so the warehouse, the email service, and billing can do their part.
The save works. Then the process crashes a millisecond later, before the publish.
Now the order exists and nobody downstream knows about it. No shipment, no receipt, no invoice. There's no error in your logs either, because your service didn't fail at anything. It saved a row and never got to tell anyone.
This is the dual-write problem, the quiet bug under most "we lost a message" incidents. The fix is two small tables, an outbox on the way out and an inbox on the way in. You need both.
Share this post & I’ll send you some rewards for the referrals.
Build for the long run (Partner)

Long-running agents need endurance.
They must endure waiting for users, and weather tool failures. They must take each new jump in model intelligence in stride.
Inngest makes long-running agents durable, observable and improvable over time.
Check out their generous free tier and a sleek local dev server for testing your workflows.
(Thanks to Inngest for partnering on this post.)
Two writes can't be made atomic, in any order
Here's the code almost everyone writes first:
await db.orders.insert(order);   // system 1: your database
await broker.publish(event);     // system 2: the message broker
The two systems don't share a transaction, so you can be wrong in two ways:
Lost message. The insert commits, then the publish fails or the process dies. The order exists and the event is gone.
Phantom message. The publish goes out, then the database write fails. You get this when you publish inside a transaction that later rolls back, or when you flip the two lines. Consumers now act on an order that doesn't exist.
Flipping the lines only swaps which failure you get. A retry around the publish doesn't help either, because a crashed process retries nothing.
The textbook fix is two-phase commit across the database and the broker. Skip it. It holds locks across network round trips, and Kafka, RabbitMQ, and SQS don't support it anyway.
The outbox turns two writes into one
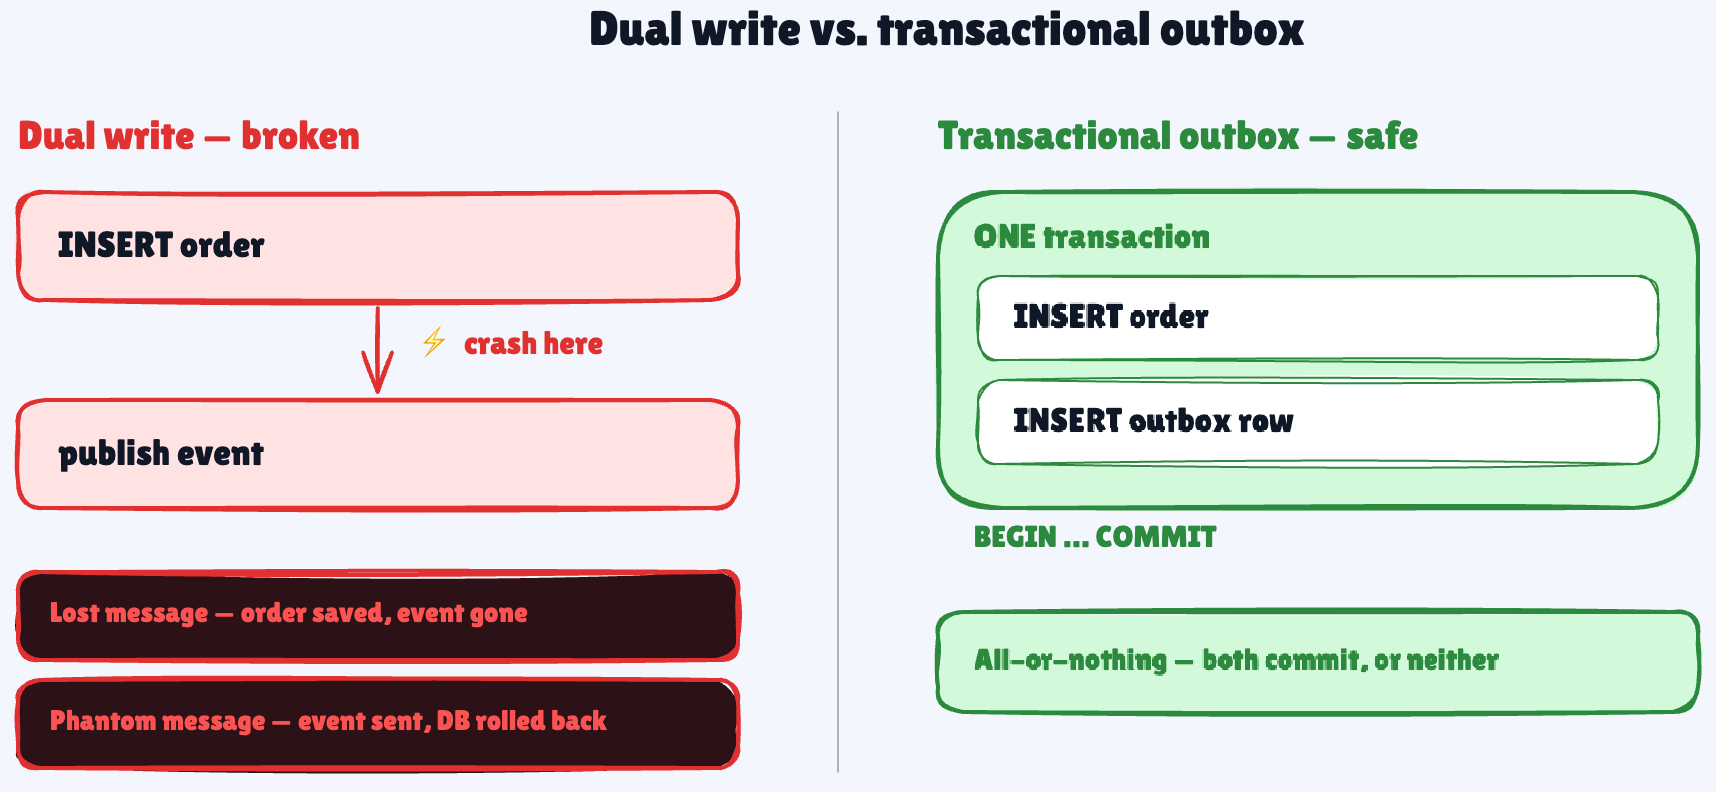
Stop publishing from the request. Write the event into an outbox table in your own database instead, in the same transaction as the order.
await db.tx(async (t) => {
  const order = await t.orders.insert({ id, userId, total });
  await t.outbox.insert({
    eventId: crypto.randomUUID(),  // a stable id that travels with the message
    aggregateId: order.id,         // becomes the message key
    type: 'OrderPlaced',
    payload: { orderId: order.id, userId, total },
  });
}); // both rows commit together, or neither does
There's no moment where the order exists without its event anymore, because there's only one write.
The outbox is a queue you keep in Postgres:
CREATE TABLE outbox (
  id           BIGSERIAL PRIMARY KEY,  -- the relay reads in this order
  event_id     UUID NOT NULL UNIQUE,   -- consumers dedup on this
  aggregate_id TEXT NOT NULL,          -- e.g. the order id
  type         TEXT NOT NULL,
  payload      JSONB NOT NULL,
  created_at   TIMESTAMPTZ NOT NULL DEFAULT now(),
  published_at TIMESTAMPTZ             -- NULL until the relay ships it
);
CREATE INDEX outbox_unpublished ON outbox (id) WHERE published_at IS NULL;
Don't skip the partial index. The relay only ever asks for unpublished rows, and without it every poll scans a table that grows with every order.
The relay is one boring loop, and it's easy to get wrong
The relay is a background worker that moves those rows to the broker:
await db.tx(async (t) => {
  const batch = await t.query(`
    SELECT * FROM outbox WHERE published_at IS NULL
    ORDER BY id LIMIT 100 FOR UPDATE SKIP LOCKED`);
  for (const row of batch) {
    // must resolve only after the broker confirms it has the message
    await broker.publish(row.type, row.aggregate_id, { ...row.payload, eventId: row.event_id });
    await t.query(`UPDATE outbox SET published_at = now() WHERE id = $1`, [row.id]);
  }
}); // select, publish, mark, then commit. One transaction.
Two mistakes quietly break it.
Splitting the select from the mark. FOR UPDATE SKIP LOCKED lets several relays run side by side, each on a different batch. The locks only live while the transaction is open, though. Run the SELECT on its own, and they vanish when it returns, so two relays publish the same rows.
Not waiting for the broker. A publish call that returns once the bytes leave your process proves nothing. Turn on publisher confirms in RabbitMQ, keep acks=all in Kafka (the default since Kafka 3.0), and mark a row only after the broker says it has the message. Otherwise, the relay marks rows as published that the broker never got, and the dual-write bug is back inside the fix.
Holding row locks during network calls is the price. Keep batches small and publish timeouts short. If that's still too much, switch to a lease (claim rows with a short UPDATE … SET claimed_at = now() … RETURNING *, publish with no locks held, then mark them).
Either way, the relay is at-least-once. Crash after a publish but before the commit, and it sends that event again on restart. The inbox exists for exactly this.
The inbox makes the second delivery a no-op
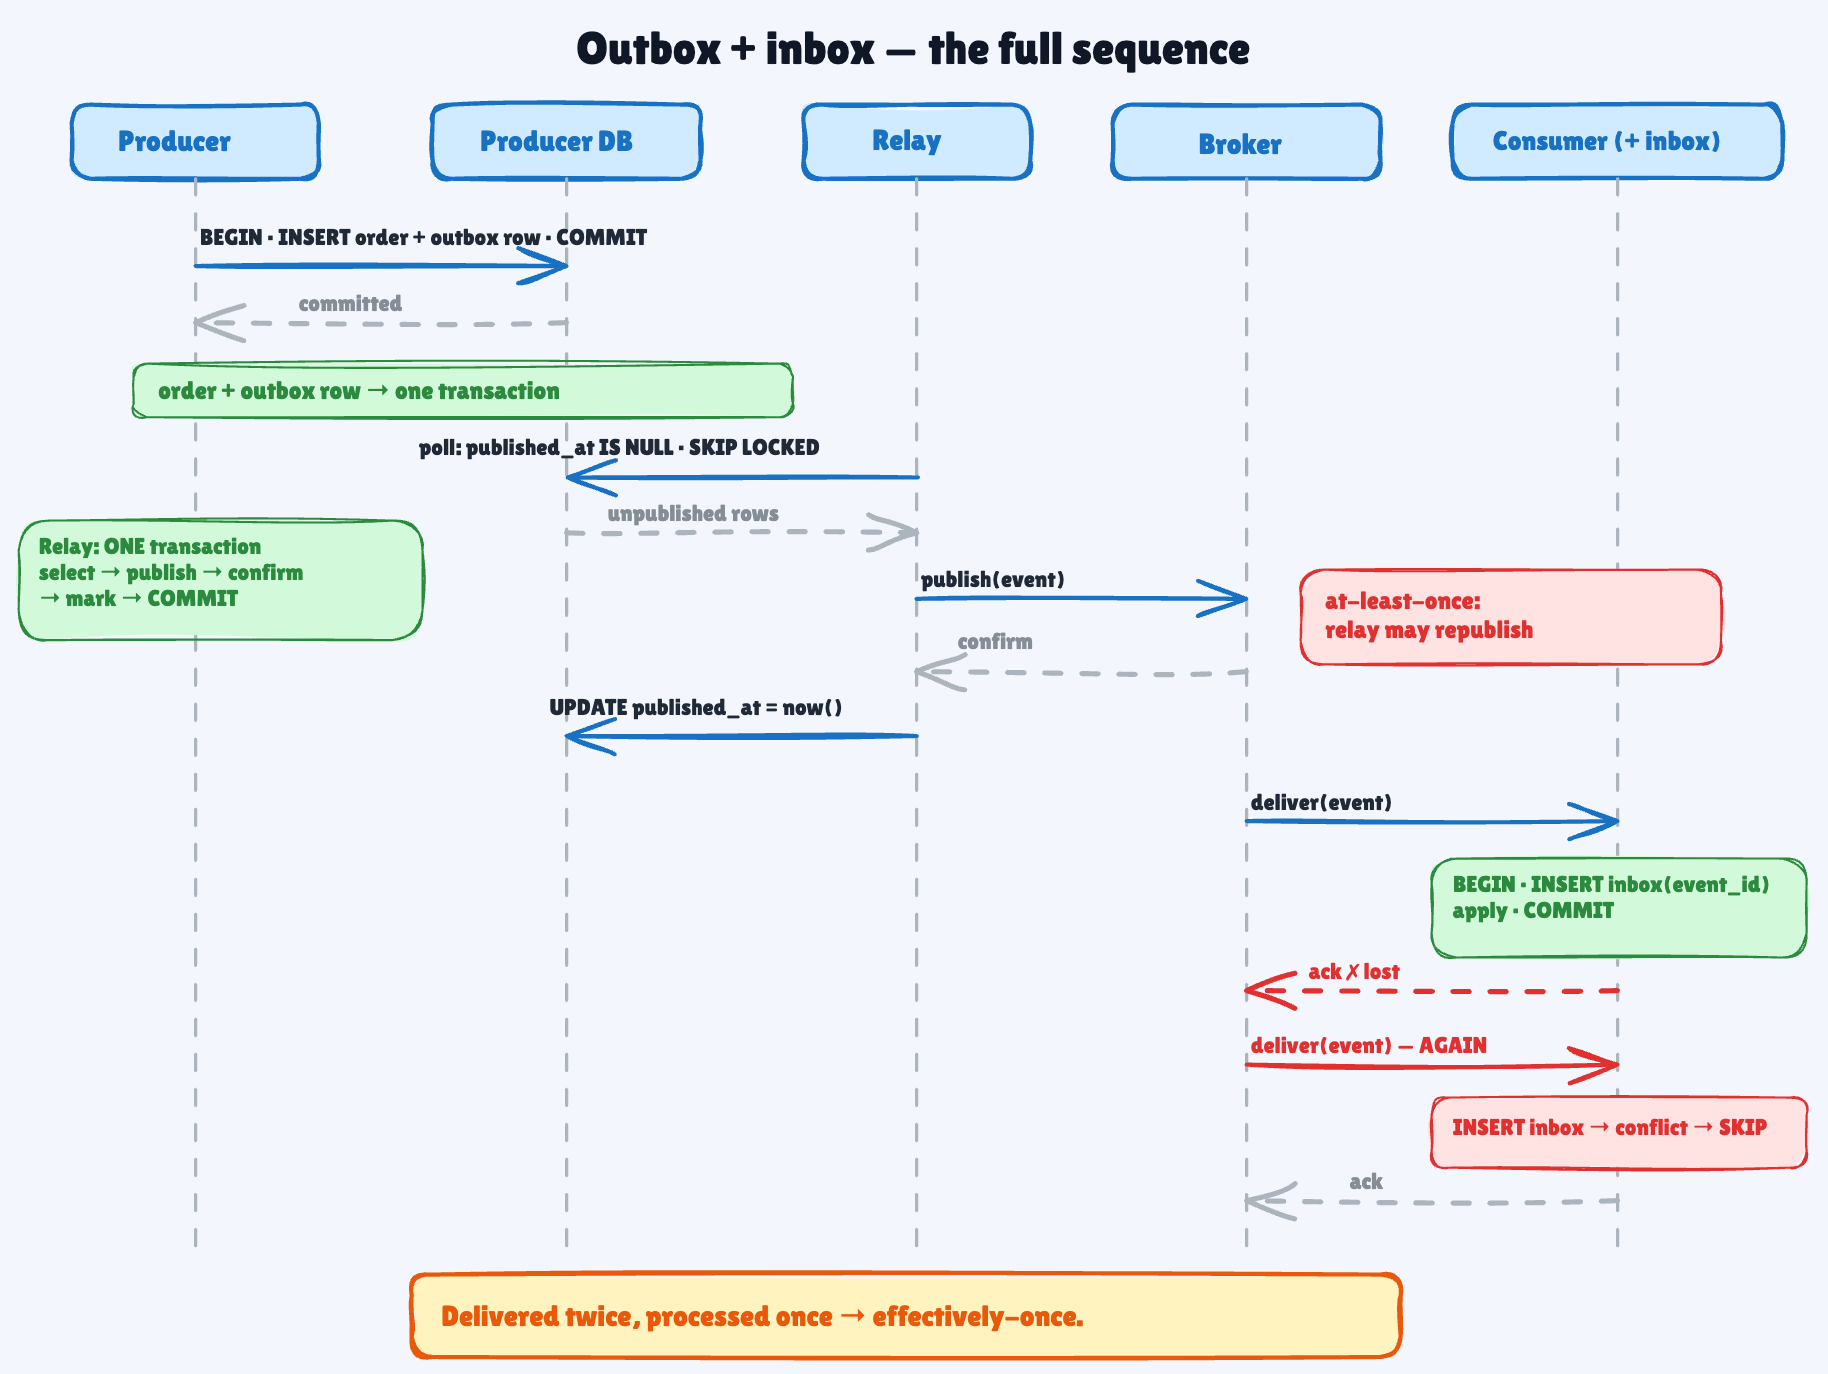
Brokers add duplicates of their own. If the network drops a consumer's ack, the broker can't tell "processed" from "lost", so it redelivers. Kafka's transactions give you exactly-once between Kafka topics and stop at your Postgres. SQS FIFO drops re-sends with the same deduplication ID for only five minutes.
Exactly-once delivery into your database doesn't exist. What you can build is effectively-once, meaning at-least-once delivery plus processing that's safe to repeat. The inbox is a table of event IDs you've already handled:
CREATE TABLE inbox (
  event_id     UUID PRIMARY KEY,   -- the id the outbox generated
  processed_at TIMESTAMPTZ NOT NULL DEFAULT now()
);
Claim the event and do the work in one transaction:
await db.tx(async (t) => {
  const claimed = await t.query(`
    INSERT INTO inbox (event_id) VALUES ($1)
    ON CONFLICT DO NOTHING RETURNING event_id`, [eventId]);
  if (claimed.length === 0) return; // seen it: skip, then ack
  await applyOrder(t, payload);     // the side effect, same transaction
});
// ack the broker only AFTER this commits
Here's how it handles each failure:
Duplicate event. The insert hits the primary key,
RETURNINGcomes back empty, and you skip.Two copies at once (say a visibility timeout expired mid-processing). The second insert waits on the first transaction's row. It skips if the first commits and does the work if the first rolls back.
Crash mid-processing. The rollback takes the inbox row with it. No ack went out, so the broker redelivers and the retry runs clean.
Crash after commit, before ack. The redelivery hits the inbox, skips, and acks.
Dedup on your event ID, never the broker's. RabbitMQ's delivery tag and SQS's receipt handle change on every delivery. Even the broker's message ID fails, because a relay republish after a crash is a brand-new message to the broker. Only the event_id from the outbox survives both kinds of duplicate.
Ack only after the commit. Ack first, crash before committing, and you've told the broker "done" for work that rolled back. That message is gone for good.
You get a true exactly-once effect only for writes in the same database, since only they share the transaction. A card charge or an email can't roll back, so each external call needs its own idempotency key. I covered that side in the idempotency guide. The same goes for an inbox kept in Redis with SET NX, because Redis can evict a key.
The edges that bite in production
Dedup isn't ordering. If
OrderCancelledcan land beforeOrderPlaced, the inbox won't save you. Sorting byidisn't enough either, since Postgres assigns ids at insert and a slow transaction can commit id 41 after id 45 shipped. Publish withaggregate_idas the message key (the Kafka partition key or the SQS FIFO message group) so one order's events go through one consumer, in sequence.Poison messages need an exit. A message that always throws redelivers forever and blocks its partition. Move it to a dead-letter queue after N attempts, and alert on DLQ depth.
Both tables grow. Delete published outbox rows after a few days. Keep inbox rows longer than any redelivery can arrive, including a replay from the DLQ a week later.
Alert on the oldest unpublished row.
now() - min(created_at)over unpublished rows is your relay's heartbeat. When it climbs, events are piling up and nobody downstream knows yet.
📌 TL;DR
Save-then-publish isn't atomic. A crash in between loses the event, or sends one for an order that doesn't exist. No ordering of the two writes fixes it.
Outbox: write the event to an
outboxtable in the same transaction as the business change. A relay ships it to the broker.Relay: select, publish, and mark in one transaction with
FOR UPDATE SKIP LOCKED, and wait for the broker's confirm before marking.Inbox: exactly-once delivery into your database doesn't exist, so claim the event ID and do the work in one transaction. Duplicates skip. Ack only after the commit.
Dedup on the
event_idyou generated, never a broker delivery tag or message ID.In production: key messages by entity for ordering, add a DLQ, clean up both tables, and alert on the oldest unpublished row.
Follow me on LinkedIn | Twitter(X) | Threads
Thank you for supporting this newsletter.
Consider sharing this post with your friends and get rewards.
You are the best! 🙏
Press the Like button if you found this post helpful